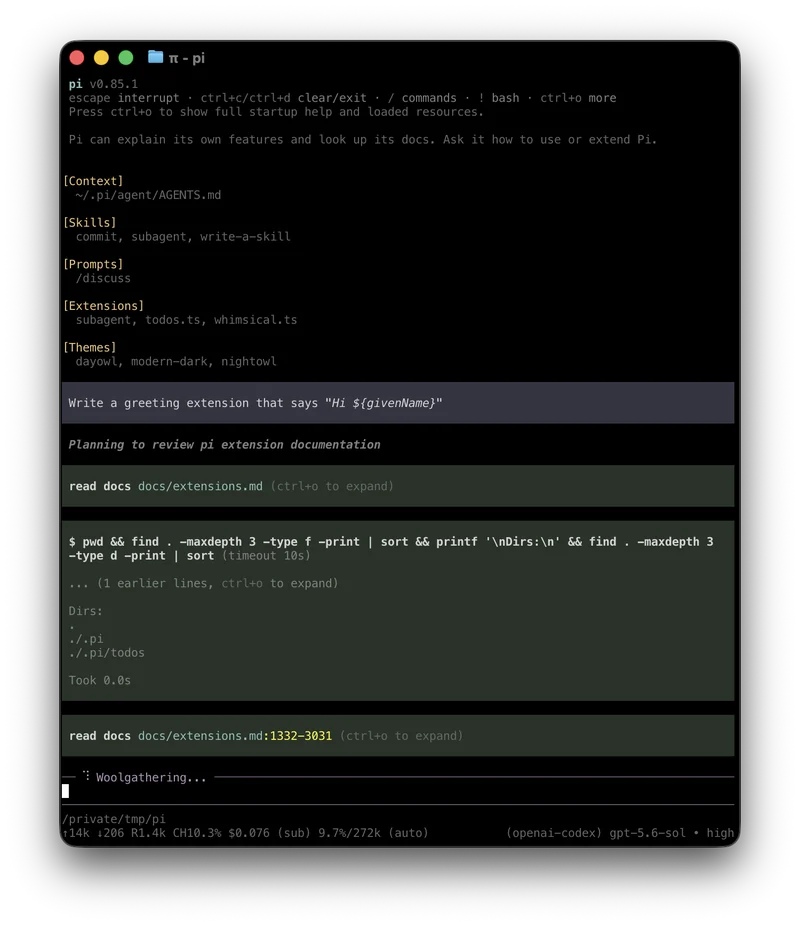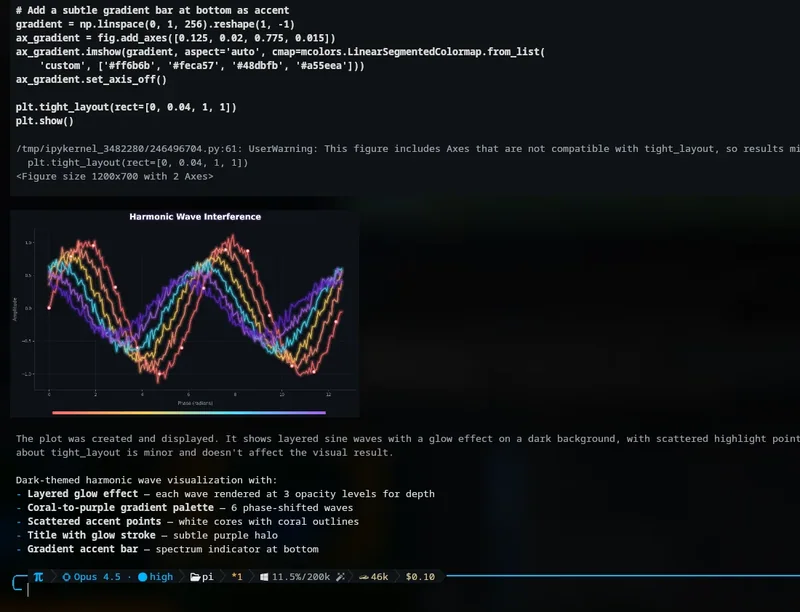
Terminal coding agent
- Price
- $17/mo billed yearly · $20 monthly
- License
- Proprietary
- Stars
- 156k
- Shipped
- 1d ago
Terminal coding agent
In the maker’s words: A project structure aware autonomous software engineer aiming for autonomous program improvement. Resolved 37.3% tasks (pass@1) in SWE-bench lite and 46.2% tasks (pass@1) in SWE-bench verified with each task costs less than $0.7.
api.github.com ↗
Not yet verified.
Counts cover stable published GitHub releases. Charts show days with at least one stable product release, so multiple releases in one day count once. Prereleases, declared nightlies and timestamped or commit-artifact builds are counted separately. Drafts and bare tags are excluded. Monorepo counts cover the verified product stream, excluding SDKs, infrastructure and sibling packages. All windows end at the recorded release snapshot. Release methodology. Collected 18 Nov 2026. Release evidence
Release days per week, last 26 weeks
A score needs at least one Hacker News mention in the last 90 days. AutoCodeRover has none yet, so it has no score and no rank. Upvotes still show their real count.
3,103 GitHub stars, read 18 Nov 2026.
Fewer than 10 votes. Votes can only raise a score: up to 20% of it reflects upvotes, graded on a curve against the most-voted tool. The square-root curve has a floor of 100 effective votes. Votes decay with a 90-day half-life. Maker self-votes do not count. Counts below 10 are hidden for display only.
We are gathering what developers say about AutoCodeRover on X, Reddit and Hacker News. Classifying it is not live yet, so there is no sentiment score and sentiment is not part of the Index score. When it is, this section shows the positive, neutral and negative split with a margin.
A sample of threads found during research: issues and discussions, not a measure of satisfaction.
A project structure aware autonomous software engineer aiming for autonomous program improvement. Resolved 37.3% tasks (pass@1) in SWE-bench lite and 46.2% tasks (pass@1) in SWE-bench verified with each task costs less than $0.7.api.github.com ↗ · read 18 Nov 2026
- 🔎 Context retrieval: The LLM is provided with code search APIs to navigate the codebase and collect relevant context.github.com ↗ · read 18 Nov 2026
For running ACR on a local issue and local codebase, prepare a local codebase and write an issue description into a file,github.com ↗ · read 18 Nov 2026
AutoCodeRover works with different foundation models. You can set the foundation model to be used with the `--model` command line argument.github.com ↗ · read 18 Nov 2026
[June 08, 2024] Added support for Gemini, Groq (thank you KasaiHarcore for the contribution!) and Anthropic models through AWS Bedrock (thank you JGalego for the contribution!).github.com ↗ · read 18 Nov 2026
| OpenAI | gpt-4o-2024-08-06 | --model gpt-4o-2024-08-06 |github.com ↗ · read 18 Nov 2026
- [April 29, 2024] Added support for Claude and Llama models. Find the list of supported models [here](#using-a-different-model)! Support for more models coming soon.github.com ↗ · read 18 Nov 2026
export ANTHROPIC_API_KEY=sk-ant-api...github.com ↗ · read 18 Nov 2026
https://docs.anthropic.com/claude/reference/getting-started-with-the-apigithub.com ↗ · read 18 Nov 2026
https://discord.gg/ScXsdE49JYgithub.com ↗ · read 18 Nov 2026
When i use ollama,i can't use command direct to ollama modle.api.github.com ↗ · read 18 Nov 2026
Why some instances get Error running command: git returned non-zero exit status 128 and how to fix it?api.github.com ↗ · read 18 Nov 2026
Replicate experiments failed with exception: RetryError[ ].api.github.com ↗ · read 18 Nov 2026
🔎 Context retrieval: The LLM is provided with code search APIs to navigate the codebase and collect relevant context.github.com ↗ · read 18 Nov 2026
For running ACR on a local issue and local codebase, prepare a local codebase and write an issue description into a file,github.com ↗ · read 18 Nov 2026
Release notesdocs.anthropic.com ↗ · read 18 Nov 2026
[August 14, 2024] On the SWE-bench Verified dataset released by OpenAI, AutoCodeRover(v20240620) achieves 38.40% efficacy, and AutoCodeRover(v20240408) achieves 28.8% efficacy. More details in the blog post from OpenAI and SWE-bench leaderboard.github.com ↗ · read 18 Nov 2026
Otherapi.github.com ↗ · read 18 Nov 2026
AutoCodeRoverSGapi.github.com ↗ · read 18 Nov 2026
AutoCodeRoverapi.github.com ↗ · read 18 Nov 2026
Alternatively, you can have a local copy of AutoCodeRover and manage python dependencies with `environment.yml`.raw.githubusercontent.com ↗ · read 18 Nov 2026
You can set the foundation model to be used with the --model command line argument.github.com ↗ · read 18 Nov 2026
3103api.github.com ↗ · read 18 Nov 2026
From the API response. No sentence to quote.api.github.com ↗ · read 18 Nov 2026
From the API response. No sentence to quote.api.github.com ↗ · read 18 Nov 2026
From the API response. No sentence to quote.api.github.com ↗ · read 18 Nov 2026
From the API response. No sentence to quote.github.com ↗ · read 18 Nov 2026
Ordered by Index score.
Terminal coding agent
Terminal coding agent
Terminal coding agent
Terminal coding agent
Terminal coding agent
Terminal coding agent
Terminal coding agent
Terminal coding agent